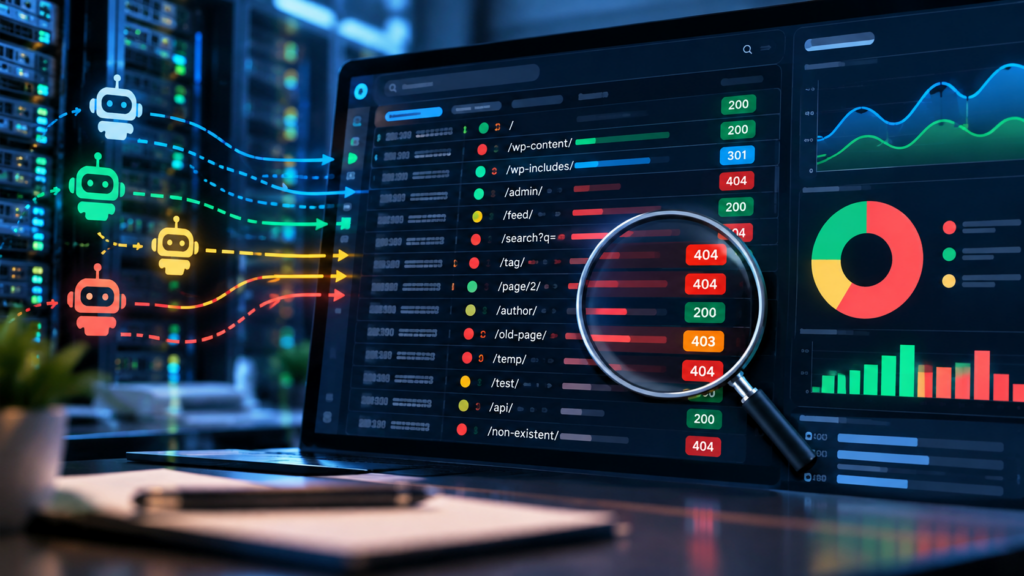
Most SEO tools tell you what a crawler could discover. Server access logs tell you what crawlers actually requested. That difference makes SEO log file analysis one of the most useful techniques for diagnosing crawl waste, broken URLs, redirect-heavy paths, and pages that search engines rarely reach.
Google describes crawl budget in terms of the URLs Google can and wants to crawl, with crawl capacity and crawl demand both affecting the result. For large or frequently changing sites, understanding the requests reaching your server can reveal problems that a normal site crawl will not show. Google’s crawl budget documentation is the best starting point for the underlying concepts.
This guide explains how to analyze access logs for SEO, what data to extract, which patterns deserve attention, and how to turn raw requests into practical technical SEO actions.
What Is SEO Log File Analysis?
SEO log file analysis is the process of examining server access logs to understand how search engine crawlers interact with a website.
An access log commonly records information such as:
- Request timestamp
- Requested URL or path
- HTTP method
- HTTP response status
- User-agent string
- Client IP address, depending on server configuration
- Referrer and response-size information when configured
For technical SEO, the most useful combination is usually crawler identity + URL + timestamp + HTTP status. Together, these fields let you ask questions such as:
- Which URLs does Googlebot actually request?
- How often are important pages crawled?
- How much crawler activity reaches 404 or 5xx responses?
- Are redirects consuming crawler requests?
- Are parameter, search, filter, or other low-value URLs being requested repeatedly?
- Which important URLs are present in the sitemap but rarely or never requested?
Why Logs Add Something a Normal SEO Crawl Cannot
A crawler such as an SEO spider starts from a controlled set of URLs and follows links according to its own rules. A server log records requests that actually reached your server. That makes the two datasets complementary rather than interchangeable.
| Data source | Best question it answers |
|---|---|
| SEO crawler | What can a crawler discover and what does the site return? |
| Search Console | What Google reports about search visibility, indexing and performance? |
| Analytics | What users do on the site? |
| Server access logs | What requests actually reached the server, including crawler requests? |
That distinction matters when diagnosing crawl behavior. A page can be technically crawlable but receive little crawler attention, while another URL can generate a large number of requests despite having little SEO value.
Log analysis therefore works particularly well alongside a technical SEO audit checklist, rather than replacing it.
When Should You Use Log File Analysis?
Log analysis is especially valuable when a site has enough crawl activity or URL complexity that patterns are difficult to see from normal reports.
Common use cases include:
- Large ecommerce catalogs
- Sites with faceted navigation or URL parameters
- Large publishing archives
- Sites with frequent migrations or URL changes
- Websites with many redirects or historical URLs
- Sites experiencing repeated 404 or 5xx responses
- JavaScript-heavy sites where rendering and crawl behavior need investigation
- Websites trying to understand how search and AI crawlers interact with their content
Google’s own guidance says smaller sites that are crawled promptly after publication generally do not need to spend much time optimizing crawl budget. Crawl-budget analysis becomes more useful as site size, update frequency, or URL complexity increases. See Google’s crawl budget guidance.
How to Perform an SEO Log File Analysis
1. Get the Right Logs
For crawl analysis, request server access logs, not only PHP error logs or application logs. Depending on your infrastructure, these may come from Apache, Nginx, a load balancer, CDN, or another reverse-proxy layer.
Before downloading anything, confirm:
- The date range covered
- Whether the log contains crawler requests
- The log format
- Whether URLs, status codes and user agents are present
- Whether requests from a CDN or proxy are included
2. Identify Search Engine Crawlers Carefully
User-agent strings are useful for grouping requests, but a user-agent string by itself is not proof of crawler identity. A request can claim to be Googlebot without actually originating from Google’s infrastructure.
For high-confidence analysis, verify important crawler traffic using the crawler provider’s recommended verification method. Google’s crawler documentation provides guidance for verifying Google requests and understanding Google’s crawler infrastructure.
Google Crawling Infrastructure documentation is the authoritative reference for this step.
3. Segment Requests by Status Code
Group crawler requests into response families:
| Status | SEO interpretation | What to investigate |
|---|---|---|
| 2xx | Successful response | Are these useful, indexable URLs? |
| 3xx | Redirect | Are redirects necessary, direct, and efficient? |
| 4xx | Client-side request error | Are bots repeatedly requesting removed or broken URLs? |
| 5xx | Server error | Are important URLs failing under crawler requests? |
A high number of 404 requests is not automatically a crawl-budget disaster. The important question is what URLs are returning 404, why crawlers are requesting them, and whether the requests are recurring.
4. Find the Most-Crawled URLs
Sort crawler requests by URL and request count. Then classify the URLs.
Useful groups include:
- Important indexable pages
- Category and collection pages
- Product pages
- Blog posts
- Pagination URLs
- Parameter URLs
- Search URLs
- Media and static assets
- Redirect targets
- 404 and other error URLs
This turns a huge log into an actionable URL inventory.
5. Compare Crawled URLs With Your Sitemap
Your XML sitemap represents URLs you consider important enough to submit to search engines. Compare that list with crawler requests.
Three useful groups emerge:
- Sitemap + crawled: the URL is being requested and is part of your intended search architecture.
- Sitemap + not crawled: investigate why an important URL receives little or no crawler activity.
- Not sitemap + frequently crawled: investigate why crawler demand is being spent on that URL pattern.
This comparison becomes especially useful when combined with an orphan-page analysis and your internal-linking strategy.
Common Crawl-Waste Patterns
1. Parameter and Filter URLs
Faceted navigation can generate a large number of URL combinations. Some combinations may be useful to users but have little or no search value.
If logs show repeated crawler requests for parameter-heavy URLs, review the site’s URL architecture, internal links, canonicalization and crawl controls. Log evidence is particularly valuable here because it shows whether the crawler is actually requesting those URLs rather than merely proving that they exist.
LogixScale already covers this topic in Faceted Navigation SEO.
2. Repeated 404 Requests
Look for URLs that repeatedly return 404 and identify where they originated. The best fix depends on the cause:
- Restore the page if it should exist.
- Update internal links if the URL is obsolete.
- Redirect a genuinely moved resource when an appropriate replacement exists.
- Remove unnecessary references to permanently deleted resources.
Do not redirect every 404 to the homepage. A redirect should point to a relevant replacement when one exists.
3. Redirect Chains
A crawler may request an old URL, receive one redirect, and then follow another redirect before reaching the final destination. Large numbers of redirecting URLs can indicate migration debt or outdated internal links.
Use logs to find frequently requested redirecting URLs, then pair the findings with a crawler that can inspect redirect chains.
4. Server Errors During Crawling
Repeated 5xx responses deserve immediate attention, especially when they affect important pages. Google explains that slow responses and server errors can influence crawl capacity. A healthy, responsive site gives Google’s systems more room to crawl when there is demand. Google’s crawl budget documentation explains the relationship between crawl capacity and site health.
Do not treat a single isolated server error as proof of a site-wide SEO problem. Look for frequency, affected URL patterns, timing, and whether the issue repeats.
5. Low-Value URLs Getting More Attention Than Important Pages
This is one of the most useful patterns to investigate. Suppose a site has important category pages that receive very little crawler activity while internal search URLs, temporary paths, or parameter combinations receive repeated requests.
The solution is usually architectural rather than a single robots.txt rule. Review internal links, URL generation, canonical signals, navigation, sitemap inclusion, and crawl controls together.
How to Turn Log Findings Into SEO Actions
Raw data is only useful when it changes a decision. Use a simple prioritization model:
| Finding | Priority | Typical action |
|---|---|---|
| Important URL returns 5xx | High | Investigate server/application failure immediately |
| Important URL repeatedly redirects | High | Update links and simplify the redirect path |
| Large parameter pattern is frequently crawled | High | Review URL generation and crawl controls |
| Many obsolete 404s are repeatedly requested | Medium | Fix internal references and relevant redirects |
| Important sitemap URLs receive little crawler activity | Medium | Review internal linking, architecture and discoverability |
| Static assets receive crawler requests | Context-dependent | Determine whether the requests are expected |
Log Analysis and Crawl Budget: What Not to Do
- Do not block URLs just because they are frequently crawled. First understand why they are being requested.
- Do not assume every 404 is harmful. Investigate the source and recurrence.
- Do not confuse crawling with indexing. A crawler visiting a URL does not mean the URL will be indexed.
- Do not rely on robots.txt as a universal cleanup tool. URL architecture and internal linking often matter more.
- Do not optimize crawl budget on a small site without evidence of a problem. Google explicitly notes that many smaller sites do not need specialized crawl-budget optimization.
- Do not trust an unverified crawler identity. User-agent strings can be spoofed.
A Practical SEO Log Analysis Checklist
- Collect an appropriate access-log sample.
- Confirm the log format and fields.
- Identify and verify major search-engine crawlers.
- Separate crawler requests from human traffic.
- Group requests by URL.
- Group requests by HTTP status.
- Find the most frequently crawled URLs.
- Find frequently crawled 4xx and 5xx URLs.
- Find frequently crawled redirecting URLs.
- Identify parameter, filter and search URL patterns.
- Compare crawler activity with the XML sitemap.
- Compare crawler activity with important internal-link targets.
- Prioritize high-impact problems.
- Fix the underlying architecture or server issue.
- Re-analyze a later log sample to confirm that the pattern changed.
How Log Analysis Fits Into a Technical SEO Workflow
Log analysis works best as one layer of a broader technical SEO system.
A practical sequence is:
Crawl the website → inspect indexability → review sitemap and internal links → analyze server logs → identify patterns → fix the underlying issue → re-crawl and re-check.
For example, if a crawl finds thousands of parameter URLs, the log tells you whether Googlebot is actually spending requests on those URLs. If a site migration creates hundreds of redirects, the log can show which legacy URLs are still being requested. If an important page is technically valid but rarely crawled, the next step is to investigate discoverability and architecture rather than simply creating another sitemap entry.
This evidence-led approach is more reliable than making broad changes based on assumptions.
Final Takeaway
SEO log file analysis turns crawler behavior from a theory into evidence. Instead of asking only whether a URL can be crawled, you can see which URLs crawlers actually request, how often they request them, and what your server returns.
For sites with meaningful crawl complexity, the most valuable findings are usually not a single magic metric. They are patterns: repeated errors, unnecessary redirects, parameter-heavy URLs, low-value paths receiving crawler attention, and important URLs that are not being reached as expected.
Use those patterns to improve the architecture rather than applying isolated fixes. For a broader foundation, continue with LogixScale’s Technical SEO resources and the Technical SEO Audit Checklist.